
Stale but Stable: Staleness-Adaptive Trust Regions for Stabilizing Asynchronous Reinforcement Learning
Junyao Yang†, Yucheng Shi‡, Zongxia Li, Zhongzhi Li, Ruhan Wang, Xiangxin Zhou, Kishan Panaganti, Haitao Mi, Leowei Liang
† Corresponding author · ‡ Project lead; source role symbols normalized
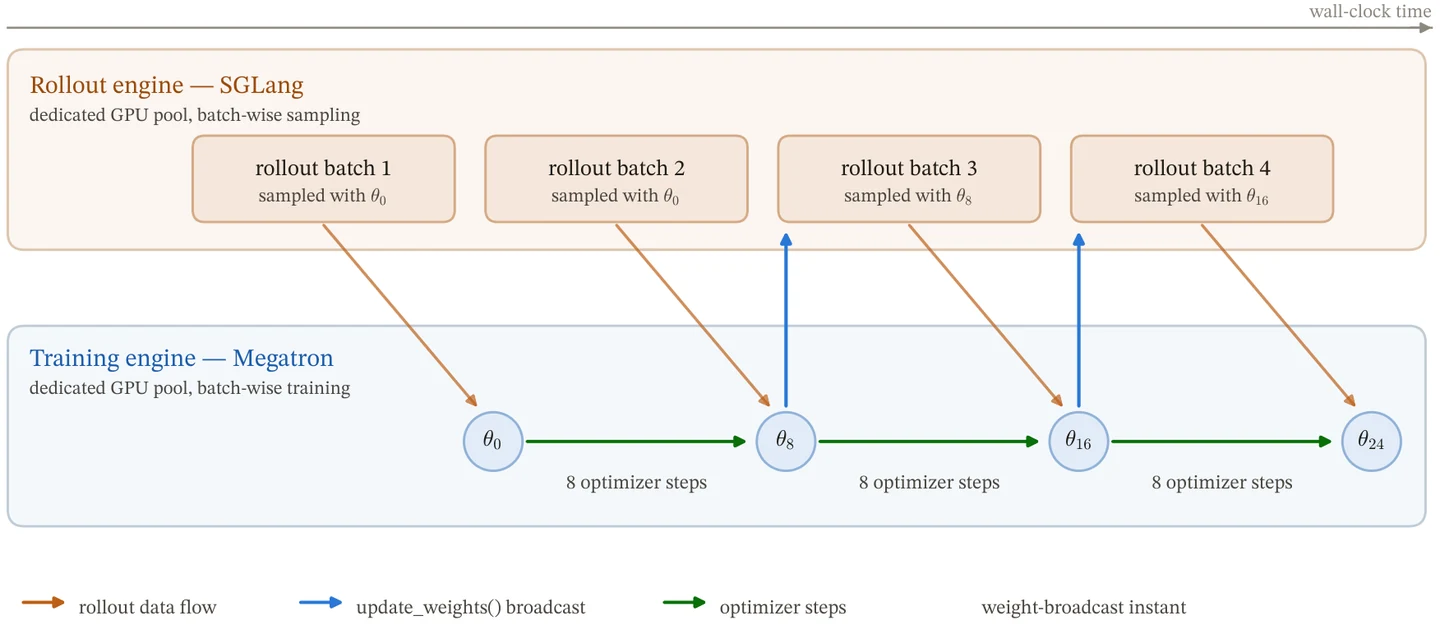
Staleness-adaptive trust regions stabilize asynchronous reinforcement learning by contracting high-mismatch outward updates. The method preserves ordinary-token behavior while controlling heterogeneous rollout staleness.