
Long-Horizon-Terminal-Bench: Testing the Limits of Agents on Long-Horizon Terminal Tasks with Dense Reward-Based Grading
Zongxia Li‡, Zhongzhi Li‡, Yucheng Shi‡, Ruhan Wang, Junyao Yang, Zhichao Liu, Xiyang Wu, Anhao Li, Chengsong Huang, Ergan Shang, Yue Yu, Ninghao Liu, Lichao Sun, Haitao Mi, Leowei Liang
‡ Core contribution (marked † in the source paper)
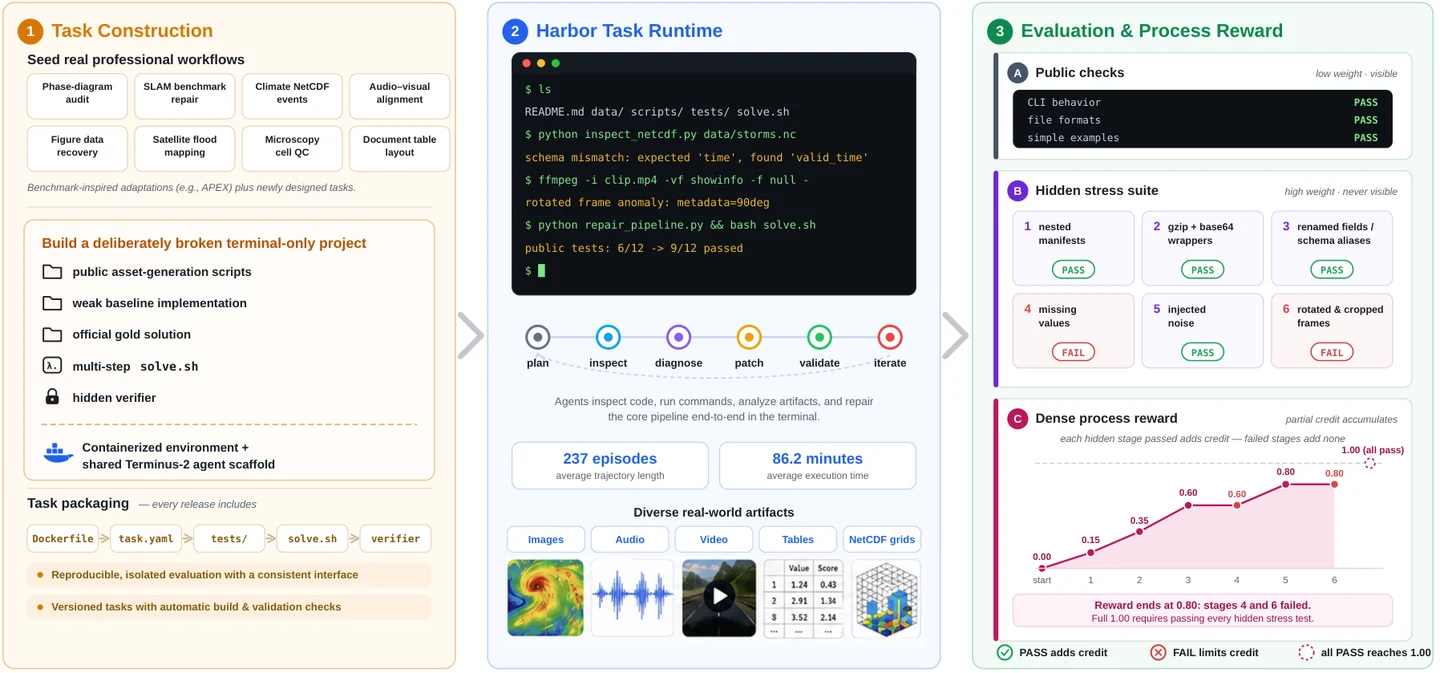
A benchmark of 46 long-horizon terminal tasks evaluates sustained agent execution using dense subtask-level rewards. Partial-credit grading exposes intermediate progress that binary task-completion metrics miss.